Fixing Context Window Limits in Financial AI Research Agents
To fix context window overflow in financial AI agents, you must move beyond raw document injection and implement semantic chunking with metadata filtering. While models like GPT-4o and o1 offer large context windows, 'lost-in-the-middle' degradation occurs when processing thousands of pages; shifting to a hybrid RAG (Retrieval-Augmented Generation) architecture ensures the model only processes the most relevant 10-20% of data with high precision.
Identifying Context Saturation in Financial Document Parsing
Financial research agents often fail not because the model is incapable, but because the context window is saturated with noise. When you ingest a 300-page 10-K filing or a series of quarterly earnings transcripts, the model's attention mechanism begins to degrade. This phenomenon, often called the 'lost-in-the-middle' problem, means the LLM prioritizes information at the very beginning and very end of the prompt, often ignoring critical financial covenants or risk factors buried in the middle sections.
Production-grade financial agents rely on optimizing the 128k to 200k token limits of models like GPT-4o and o1. If your agent is returning 'I cannot find that information' or hallucinating numbers that don't exist in the source text, you are likely hitting an attention bottleneck rather than a lack of reasoning capability. You must distinguish between a hard token limit error and a soft attention failure to apply the correct fix.
Diagnostic Triage for Context and Retrieval Errors
Before refactoring your entire pipeline, identify the exact failure mode. Context issues typically manifest in three ways: hard API errors, semantic drift, or retrieval noise. Use the following diagnostic table to map your symptoms to the root cause and the required engineering response.
| Log / Error Message | What It Means | Next Verification Command / Fix |
|---|---|---|
context_length_exceeded | Total tokens (input + output) exceed model limit. | Implement recursive chunking or RAG. |
rate_limit_reached (429) | TPM/RPM quota exhausted for your tier. | Implement exponential backoff or check ChatGPT rate limits. |
| Hallucinated 'Not Found' | The relevant chunk was not retrieved or was lost in the middle. | Increase top_k or use a reranker model. |
| Inconsistent formatting | Context window is too crowded for the system prompt to hold. | Move formatting rules to a separate 'clean-up' agent. |
To isolate the issue, run a 'needle-in-a-haystack' test. Insert a unique, non-financial fact (e.g., 'The CEO's favorite color is purple') into the middle of a 50,000-token financial document and ask the agent to retrieve it. If it fails, your current context management strategy is insufficient for high-stakes research.
Implementing Semantic Chunking for High-Precision RAG
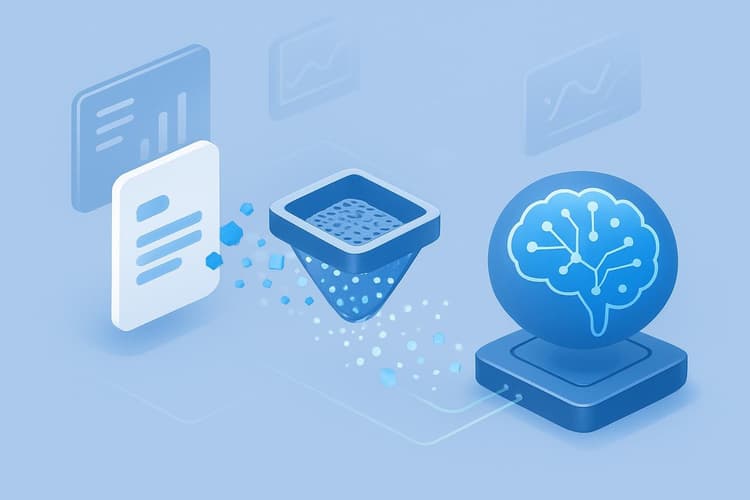
The most effective fix for context overflow is replacing naive character-based splitting with semantic chunking. Naive splitting often breaks a critical balance sheet table in half, rendering the data useless for the LLM. Semantic chunking uses a smaller embedding model to identify natural breaks in the text—such as the end of a section or a change in topic—ensuring that each chunk sent to the model is a complete, coherent unit of information.
import time
import logging
from openai import OpenAI

client = OpenAI(api_key="your_api_key")

def robust_query_with_retry(model, messages, max_retries=3):
    """
    Executes a query with exponential backoff for transient 429/5xx errors.
    Does NOT retry on 400 errors (like context_length_exceeded).
    """
    for attempt in range(max_retries):
        try:
            response = client.chat.completions.create(
                model=model,
                messages=messages,
                temperature=0
            )
            return response.choices[0].message.content
        except Exception as e:
            # Only retry on rate limits or server errors
            if "rate_limit" in str(e) or "server_error" in str(e):
                wait_time = (2 ** attempt) + 0.5 # Exponential backoff with jitter
                logging.warning(f"Transient error: {e}. Retrying in {wait_time}s...")
                time.sleep(wait_time)
            else:
                # Hard fail for context_length_exceeded or auth errors
                logging.error(f"Permanent error: {e}")
                raise e
    return None
By ensuring that your chunks are correctly sized (typically 1,000 to 2,000 tokens) and include a 10-15% overlap, you provide the LLM with enough surrounding context to understand the data without overwhelming its attention mechanism. This strategy is essential for agents that must compare year-over-year performance across multiple filings.
Leveraging Metadata Filters to Reduce Token Noise
One common mistake in financial AI agents is performing a 'global' search across all documents for every query. This floods the context window with irrelevant data from the wrong fiscal year or unrelated subsidiaries. To fix this, implement metadata-aware retrieval. Every document chunk in your vector database should be tagged with attributes like ticker, fiscal_year, document_type, and page_number.
When a user asks, 'What were the 2024 capital expenditures for NVIDIA?', your agent should first use a 'router' LLM to extract the parameters (ticker: NVDA, year: 2024). The system then queries the vector database using these filters. This reduces the candidate pool from 100,000 chunks to 50, and ensures that the context window only contains the exact pages relevant to the query. This precision is what allows platforms like Hebbia to process massive datasets without the 'hallucination drift' common in generic AI tools. If you encounter issues with new features not appearing in your API calls, verify your ChatGPT feature availability to ensure your model version supports the latest reasoning capabilities.
Verification and Latency Benchmarking for Financial Workflows
Once you have implemented semantic chunking and metadata filtering, you must verify the fix using a structured benchmarking suite. In financial research, latency is often a secondary concern to accuracy, but excessive retrieval steps can make an agent feel sluggish. Measure your 'Time to First Token' (TTFT) and your 'Retrieval Precision' (the percentage of retrieved chunks that actually contain the answer).
- Accuracy Check: Run 50 known-answer queries against your processed SEC documents. Target an accuracy rate of >95%.
- Context Density Check: Monitor the average token count of your final prompts. If you are consistently hitting >80% of the model's limit, your chunking is too aggressive or your filters are too broad.
- Latency Check: Ensure that the routing and retrieval steps add no more than 2-3 seconds to the total response time. If latency is high, consider using a faster embedding model like
text-embedding-3-smallfor the initial retrieval phase.
Verdict: Choosing Between Long-Context and RAG Architectures
For financial research, the verdict is clear: Never rely on raw long-context injection alone. While it is tempting to simply 'stuff the prompt' with a 100,000-token document, the resulting degradation in reasoning and the high cost of input tokens make it unsustainable for enterprise use.
Use a Long-Context approach only for single-document summarization where the entire narrative flow is required. Use a Hybrid RAG approach (with semantic chunking and metadata filters) for any workflow involving multi-document comparison, trend analysis, or high-precision data extraction. This architecture not only solves the context overflow problem but also provides a clear audit trail—allowing your users to see exactly which chunk of which document provided the answer.
Frequently Asked Questions
Why does my agent hallucinate even with a 128k context window?
This is usually due to 'context saturation' or 'lost-in-the-middle' syndrome. When a prompt is too large, the model's attention mechanism struggles to weigh all tokens equally, often ignoring data in the middle. Semantic chunking solves this by providing only the most relevant snippets.
Can I use vector databases to bypass token limits entirely?
Yes. Vector databases allow you to store millions of documents and retrieve only the top-k most relevant chunks (e.g., the top 10 paragraphs) to fit within a single model call, effectively giving the agent an 'infinite' external memory.
How do I handle tables in financial PDFs during chunking?
Standard text splitters often break tables. Use a specialized parser (like Unstructured or LlamaParse) to convert tables into Markdown format before chunking. Markdown preserves the structural relationships between rows and columns for the LLM.
Get the Weekly SMB AI & SaaS Brief
Practical software benchmarks, prompt templates, and ROI breakdowns delivered every Tuesday. No fluff, unsubscribe anytime.